Cohere API Review: Command A+, RAG, Rerank, Embed, Parse, and Private Deployment in 2026
Information current as of September 29, 2026.
Cohere stands apart from many companies commonly grouped with OpenAI, Anthropic, or Google. Its platform can generate text, work with images, call functions, and build AI agents, but Cohere's focus has long been enterprise search, RAG, and private model deployment.
That specialization became even more pronounced in 2026. The latest Command A+ brings together reasoning, vision, multilingual generation, tool use, and citations. Embed 4 creates a shared vector representation for text and images; Rerank 4 reorders search results; Parse 5 turns complex PDFs and forms into structured Markdown; and the North family now includes dedicated coding and machine-translation models.
Cohere also offers far more deployment options than a standard public API. You can use the shared Cohere Platform, a dedicated single-tenant Model Vault, AWS, Azure, OCI, your own VPC, or even a fully on-premises installation in an isolated network.
That is why it is more useful to view Cohere API not as “another ChatGPT API,” but as a set of components for enterprise AI systems, especially products built around internal documents, search, source citations, and data-residency requirements.
This article reviews Cohere's current models and APIs, pricing, Chat V2, OpenAI compatibility, tool use, RAG, Embed, Rerank, Parse, Transcribe, registration, privacy, and private deployment options.
What Is the Cohere Platform?
The simplest way to use Cohere is through the public Cohere Platform.
The main API is available at:
https://api.cohere.com
New code uses API V2, whose main generative endpoint is:
POST /v2/chat
The Cohere Platform provides several independent model families:
- Command — generation, reasoning, tool use, vision, and RAG;
- North — specialized models for coding, translation, and other tasks;
- Embed — embeddings for semantic search and retrieval;
- Rerank — reordering search results;
- Parse — parsing PDFs, forms, presentations, and images;
- Cohere Transcribe — speech-to-text;
- Aya — multilingual research models.
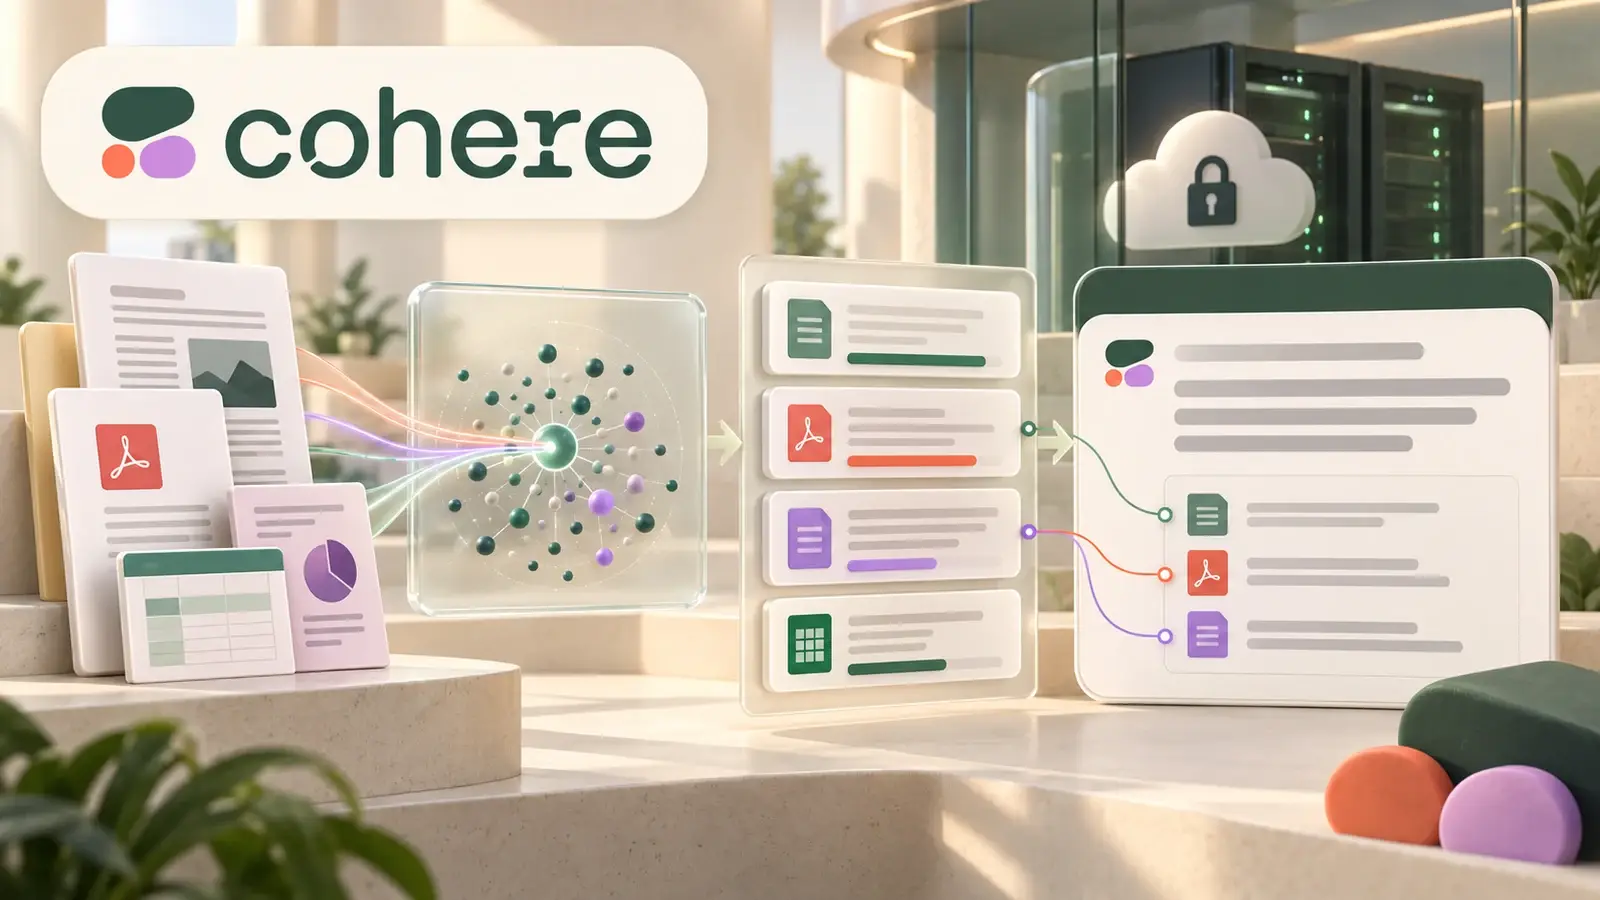
Command and the Chat API are enough for a simple AI assistant. Cohere's main strength emerges when these components work together: Parse prepares documents, Embed turns them into vectors, Rerank selects the most relevant results, and Command produces an answer with precise citations.
Command A+ — the Current Flagship Model
In May 2026, Cohere released Command A+:
command-a-plus-05-2026
It is the first Mixture-of-Experts model in the Command family, with 218 billion total parameters and about 25 billion active parameters.
| Parameter | Command A+ |
|---|---|
| Context window | 128K tokens |
| Maximum output | 64K tokens |
| Input | Text, images |
| Output | Text |
| Languages | 48 |
| Reasoning | Yes |
| Function calling | Yes |
| Structured Outputs | Yes |
| Citations | Yes |
| Open weights | Yes, Apache 2.0 |
The model supports all official EU languages, as well as Russian, Ukrainian, Chinese, Japanese, Korean, Arabic, Vietnamese, and several others.
Cohere positions Command A+ as the strongest model in the family for agentic workloads, reasoning, tool use, and multilingual enterprise scenarios.
It also has an unusual feature: A+ was designed not only for a hosted API, but also for efficient private deployment. Cohere says it can run on a single B200 or two H100 GPUs, which matters for a model of this class in enterprise infrastructure.
Command A+ Does Not Have a Standard Pay-as-You-Go Rate
This is a notable difference from OpenAI or Anthropic.
Command A+ is available through the regular Cohere API for free within rate limits, for both trial and production keys. However, this shared API is intended primarily for evaluation and limited usage.
For full production use, Cohere recommends deploying Command A+ through Model Vault or discussing deployment with sales.
That means A+ currently has no simple shared production API rate such as:
$X input / $Y output per 1M tokens
In Model Vault, the model is billed by dedicated infrastructure:
| Tier | Price |
|---|---|
| L | $17.50 / hour |
| XL | $32.50 / hour |
For an enterprise product, this is a fundamentally different cost model. Instead of paying for each token, the organization rents a defined amount of inference capacity and gets predictable performance.
Command A
The previous-generation Command A is still available:
command-a-03-2025
It has a longer context window of 256K tokens, but a much smaller maximum output of 8K.
The standard Cohere API rates for Command A are:
input:   $2.50 / 1M tokens
output:  $10.00 / 1M tokens
The model has 111 billion parameters and is designed primarily for:
- enterprise agents;
- tool use;
- RAG;
- multilingual generation;
- structured responses.
Command A remains useful when you need a straightforward self-service production API with clear token-based pricing. For a new project, however, compare it separately with Command A+: A+ is newer, multimodal, and supports a much longer output.
Command A Reasoning, Vision, and Translate
Before A+, Cohere developed several specialized Command A variants.
Command A Reasoning is a separate reasoning model for complex, multi-step tasks.
Command A Vision is a version that accepts images.
Command A Translate is a specialized machine-translation model covering 23 languages.
Command A+ effectively brings the main capabilities of these models together in one architecture: reasoning, vision, translation, and agentic tool use.
For a new general-purpose application, Cohere presents A+ as the main model in the family. Specialized variants can still be useful where a production workflow is already built around them or deployment is optimized for a particular model.
North — a New Family of Specialized Models
In 2026, Cohere began actively developing another family: North.
Unlike Command, a general-purpose generative model, North consists of purpose-built models for specific workflows.
Two models are particularly interesting.
North Mini Code
Model ID:
north-mini-code-1-0
This is a 30B MoE model with about 3 billion active parameters, designed for agentic software engineering.
Specifications:
context:     256K
max output:   64K
license:      Apache 2.0
The model was trained to work inside a coding harness: terminal tools, repository-level modifications, multi-turn software engineering, and autonomous coding tasks.
North Mini Code is available through a free API for evaluation and has open weights. For production, Cohere offers Model Vault.
Its small number of active parameters makes it particularly interesting for local or private deployment.
North Small Translate
This is a separate MoE machine-translation model:
north-small-translate-1-0
Its specifications are:
218B total parameters
25B active parameters
16K context
16K max output
50+ languages
The model is also available through the Cohere API for free within trial limits.
Its open weights are released for non-commercial use under CC BY-NC 4.0. For commercial production, Cohere offers Model Vault or separate licensing terms.
Chat API V2
Cohere's main generative API looks familiar:
curl https://api.cohere.com/v2/chat \
  -H "Authorization: Bearer $COHERE_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "command-a-plus-05-2026",
    "messages": [
      {
        "role": "user",
        "content": "Briefly explain the difference between REST and GraphQL."
      }
    ]
  }'
Chat V2 uses standard roles:
system
user
assistant
tool
The API supports streaming, Structured Outputs, tools, reasoning, and document inputs.
Architecturally, it is still a stateless chat endpoint: the application builds the message list and manages conversation history itself.
Cohere has no direct equivalent of the OpenAI Responses API with server-managed conversation state and background responses. Instead, Cohere puts more emphasis on the standard Chat API, tool orchestration, and its enterprise North products.
OpenAI-Compatible API
For migrating existing OpenAI code, Cohere provides a separate compatibility endpoint:
https://api.cohere.ai/compatibility/v1
Example:
from openai import OpenAI

client = OpenAI(
    base_url="https://api.cohere.ai/compatibility/v1",
    api_key="COHERE_API_KEY",
)

response = client.chat.completions.create(
    model="command-a-plus-05-2026",
    messages=[
        {
            "role": "user",
            "content": "Explain dependency injection."
        }
    ],
)

print(response.choices[0].message.content)
Supported features include:
- Chat Completions;
- streaming;
- function calling;
- Structured Outputs;
- embeddings;
- audio transcription.
For reasoning through the OpenAI-compatible API, only these values are currently supported:
none
high
That means low and medium, familiar from some other APIs, are not accepted.
The compatibility API is useful for quickly testing Cohere without refactoring, but Cohere's native Chat V2 is more convenient for Cohere-specific RAG features and citations.
Reasoning
Modern Command models can reason before producing a final answer.
With the native API, thinking is enabled through Cohere parameters. Through OpenAI compatibility, use:
{
  "reasoning_effort": "high"
}
Reasoning is particularly useful for tool use, document analysis, planning, and agentic workflows.
For simple extraction or short text generation, however, reasoning increases latency and does not always provide a practical benefit. Enable it based on your own evaluations instead of turning it on automatically for every request.
Function Calling and Agents
Command can select application functions using standard tool calling.
For example:
{
  "type": "function",
  "function": {
    "name": "get_order",
    "description": "Retrieve information about an order",
    "parameters": {
      "type": "object",
      "properties": {
        "order_id": {
          "type": "string"
        }
      },
      "required": ["order_id"]
    }
  }
}
The model can return a call to get_order; the backend performs the actual operation and then passes the result back to the Chat API.
Cohere also supports multi-step tool use: the model can call several tools in sequence, using one step's result to decide what to do next.
This makes it possible to build agents for CRM systems, internal tools, search, analytics, and other business workflows.
Strict Tools
A particularly useful production setting is:
strict_tools = true
It forces generated tool calls to conform strictly to the specified schemas.
Cohere guarantees:
- no invented tool names;
- no unknown parameters;
- required parameters are present;
- parameter types match the specified JSON Schema.
This reduces the amount of defensive parsing and prompt engineering otherwise needed around function calling.
Structured Outputs
Cohere supports Structured Outputs in two forms.
JSON Mode
The model is guaranteed to return valid JSON:
{
  "response_format": {
    "type": "json_object"
  }
}
JSON Schema
You can provide an object structure and receive output that matches the schema.
This is useful for:
- extraction;
- classification;
- filling DTOs;
- document processing;
- CRM;
- the next step in an agent workflow.
Structured Outputs are supported by Command A+, Command A, and several earlier Command models.
The previously mentioned strict_tools works separately for function-calling arguments.
Citations — One of Cohere's Strongest Features
Citations in Cohere are more than links formatted in text. Command can return a relationship between a specific span in the answer and a specific document or tool result.
For example, the backend can pass several documents to the model:
{
  "documents": [
    {
      "data": {
        "title": "Return policy",
        "text": "Customers may return an item within 14 days."
      }
    }
  ]
}
Cohere can indicate exactly which span of its answer is based on that document.
The same approach works with tool results.
For enterprise RAG, this is more reliable than an instruction such as “add [1], [2] after each claim.” Citation metadata is part of the API response structure.
Streaming offers two modes:
accurate— citations are produced after the answer with more precise span matching;fast— lower additional latency.
Cohere Is Particularly Strong at RAG
Cohere has historically invested heavily in retrieval pipelines.
A classic architecture looks like this:
documents
↓
Parse
↓
Embed
↓
vector database
↓
retrieval
↓
Rerank
↓
Command
↓
answer with citations
Each layer handles a separate task.
This is somewhat more complex than “upload files to built-in File Search,” but it gives you more control over retrieval, the index, chunking, and ranking.
This architecture may be excessive for a small chatbot. For enterprise search across diverse documents, it creates a clearer separation of responsibilities.
Embed 4
The current embedding model is:
embed-v4.0
It is multimodal: it can map not only text but also images and mixed text/image content—such as screenshots of PDF pages or presentations—into a shared semantic vector space.
Key specifications:
context: 128K
dimensions: 256, 512, 1024, or 1536
languages: 100+
Cosine similarity, dot product, and Euclidean distance are supported.
Current API pricing:
text:   $0.12 / 1M tokens
image:  $0.47 / 1M image tokens
Embed 4 is useful for:
- semantic search;
- clustering;
- classification;
- recommendations;
- RAG;
- multimodal retrieval.
One particularly interesting capability is building a shared embedding for text and visual document content without a separate OCR pipeline.
Rerank 4
Embedding search finds approximately relevant documents quickly, but the top results are not always in the right order.
For a second stage, Cohere offers Rerank 4:
rerank-v4.0-pro
rerank-v4.0-fast
Both models:
- are multilingual;
- support semi-structured JSON;
- have context up to 32K;
- work for text search and RAG.
Fast is optimized for latency and throughput.
Pro is optimized for the highest ranking quality.
On the current first-party API, one billing unit is a query with up to 100 documents after chunking. Long documents are split automatically: if a document and query together exceed about 500 tokens, each chunk counts as a separate document.
Current list rates are approximately:
Rerank 4 Fast: $2.00 / 1,000 searches
Rerank 4 Pro:  $2.50 / 1,000 searches
So in RAG, Rerank costs should be calculated separately from the LLM. At 100,000 user searches per month, even one rerank call per query becomes a noticeable cost.
Why Use a Separate Reranker?
Why use embedding search and then pay for a second model call?
Embeddings quickly find candidates among millions of documents. For example, a vector database returns the top 50.
Rerank receives only those 50 results and scores them more precisely against the specific user query.
A typical flow looks like this:
1,000,000 documents
↓
vector search
↓
top 50
↓
Rerank
↓
top 5
↓
Command
This often produces better quality than either a huge prompt containing dozens of documents or vector similarity without an additional relevance check.
Parse 5
In August 2026, Cohere released a dedicated document-intelligence model:
parse-v5.0
This is a multimodal model with 2.3 billion parameters that turns complex documents into structured data.
Supported formats:
- PDF;
- PPT;
- JPEG.
Parse can extract:
- text in the correct reading order;
- tables;
- lists;
- forms and key-value pairs;
- images and captions;
- page boundaries;
- element positions;
- bounding boxes.
Output can be regular Markdown or structured blocks.
For example, a table is returned as HTML together with its coordinates on the page and a description.
For loading enterprise documents into RAG, this is much more reliable than a standard plain-text PDF extractor.
Compass
Cohere also sells Compass, a higher-level product built on Parse, Embed, and Rerank.
It is no longer just a model endpoint, but an enterprise search and discovery system with:
- document parsing;
- a managed index;
- semantic retrieval;
- reranking;
- search across business data.
Compass pricing is customized through sales.
If a company wants to manage Pinecone, Qdrant, PostgreSQL/pgvector, or another vector store itself, it can use only Embed + Rerank. For a managed enterprise search stack, Cohere offers Compass.
Cohere Transcribe
In March 2026, Cohere released its own speech-to-text model:
cohere-transcribe-03-2026
It is an open-weight ASR model with 2 billion parameters.
It supports 14 languages:
- English;
- German;
- French;
- Italian;
- Spanish;
- Portuguese;
- Greek;
- Dutch;
- Polish;
- Vietnamese;
- Chinese;
- Arabic;
- Japanese;
- Korean.
The maximum file size is 25 MB.
There are limitations: the model currently does not provide automatic language detection, speaker diarization, or timestamps.
Through the shared Cohere API, Transcribe is available free for evaluation within rate limits. For production, Cohere offers Model Vault.
Cohere Transcribe Arabic
In July, Cohere introduced the specialized model:
cohere-transcribe-arabic-07-2026
It is optimized for Arabic dialects, accents, Arabic-English code-switching, and distant speech.
The model is also released with open weights under Apache 2.0.
For businesses in Middle Eastern markets, this is a distinct Cohere advantage: the company is developing not only general multilingual models, but also specialized language-focused models.
North, Command, and Transcribe Can Run Locally
Open weights are becoming a visible part of Cohere's strategy.
Command A+ is released under Apache 2.0.
North Mini Code is Apache 2.0.
Cohere Transcribe is Apache 2.0.
Cohere Transcribe Arabic is Apache 2.0.
Some other models have more restrictive licenses. For example, North Small Translate is currently released with open weights under CC BY-NC 4.0 for non-commercial use.
So it would be inaccurate to say that “all Cohere models are open source for any commercial use.” Check the license for each specific model repository.
Private Deployment — Cohere's Key Differentiator
Most AI APIs provide a cloud endpoint, while enterprise deployment is handled as a separate special project.
At Cohere, private deployment is one of the platform's main components.
There are four primary options:
- Cohere Platform.
- Cloud AI Services.
- Private Cloud / VPC.
- On-premises.
Public Cohere Platform
The simplest API. Cohere operates the model and infrastructure.
Cloud AI Services
Models are available through:
- AWS Bedrock;
- AWS SageMaker;
- Microsoft Azure AI Foundry;
- Oracle OCI Generative AI.
The specific models and features depend on the cloud provider.
Private Cloud / VPC
The Cohere stack is deployed inside the customer's own cloud account—for example, AWS, Azure, GCP, or OCI.
Data can remain inside the company's VPC.
On-Premises
Cohere supports deployment entirely on the customer's own hardware, including air-gapped environments with no external network access.
For banks, government systems, industrial organizations, or companies with strict confidentiality requirements, this can matter much more than a benchmark difference between two frontier models.
Model Vault
Between the shared API and fully private deployment, there is another option: Model Vault.
It is single-tenant infrastructure managed by Cohere.
An organization gets a dedicated endpoint without having to manage Kubernetes and GPUs itself.
Two modes are available.
Standard Vault
The model runs on dedicated infrastructure, with data protected in transit and at rest.
Model Vault Encrypted
The stricter option uses confidential-computing hardware, end-to-end encryption, and remote attestation.
As of the end of September 2026, Encrypted Vault is in beta and available free to design partners; GA pricing will be announced later.
Model Vault Pricing
Here, Cohere moves from token-based pricing to instance pricing.
Examples of Standard Vault pricing:
| Model | Tier | Price |
|---|---|---|
| Command A+ | L | $17.50 / hour |
| Command A+ | XL | $32.50 / hour |
| Command A | L | $40 / hour |
| Command A | XL | $48 / hour |
| Command A Reasoning | L | $48 / hour |
| North Mini Code | L | $7.50 / hour |
| North Mini Code | XL | $10.50 / hour |
| Embed 4 | Small | $4 / hour |
| Embed 4 | Medium | $5 / hour |
| Rerank 4 Pro | Medium | $5 / hour |
| Rerank 4 Pro | Large | $10 / hour |
| Parse 5 | Medium | $4 / hour |
Fixed and Flex plans, monthly and annual commitments, and autoscaling are available.
For a large, steady enterprise workload, this model may be cheaper than a public per-token API. More importantly, it provides isolation and predictable capacity.
Trial API Key
You can register through the Cohere Dashboard.
After you create an account, the system automatically issues a Trial API key.
It is:
- free;
- intended for prototyping and evaluation;
- subject to rate limits;
- not allowed for production or commercial use.
A typical Chat API trial limit is 20 requests per minute, with an overall monthly limit of 1,000 API calls.
Embed, Rerank, Parse, and other endpoints have separate limits.
This is useful for testing: before adding billing, you can try Chat, embeddings, reranking, Parse, and Transcribe.
Production API Key
A commercial product requires a Production key.
The organization's owner opens:
Billing and Usage
→ Get Your Production key
→ Go to Production
You must agree to the SaaS terms, confirm the Usage Policy, and specify whether the project falls into a sensitive use case.
If no additional review is required, the production key is created immediately. For sensitive use cases, Cohere may temporarily keep trial-level rate limits in place until its safety team completes a manual review.
Production APIs for regular supported models use pay-as-you-go billing.
Cohere invoices:
- at the end of the calendar month;
- or earlier if the outstanding balance reaches $250.
Command A+ and New Models Need Separate Production Planning
There is an important detail.
A Production key does not, by itself, turn the shared Command A+ API into an unlimited pay-as-you-go endpoint.
For A+, Command A Reasoning, some North models, and newer models, the shared production API still has evaluation-oriented limits. For actual production, Cohere recommends contacting sales and using Model Vault.
So before building a product around a particular new model ID, check not only “is the model available in Chat API?” but also which production deployment is supported for it.
This is one of the main Cohere-specific details in 2026.
Registration and Access from Different Countries
You can get a Cohere trial key by registering an account. Production requires an organization, billing, and acceptance of commercial terms.
I did not find a separate comprehensive country list in Cohere's public documentation like the Geographic Use Policy for Meta Model API, which explicitly names Russia as a restricted territory.
That does not mean the service is automatically available in every jurisdiction. Users must comply with applicable laws, sanctions, and Cohere's terms; actual production billing also depends on organization registration and the payment method.
For a project in Russia, it is reasonable to check direct Cohere Platform access before committing to it in production: register an account, check dashboard access and the Go to Production flow for the specific organization, and confirm that Cohere accepts the available payment method.
If the direct SaaS Platform is inconvenient, another option is a cloud provider or private deployment. For example, Cohere models are available through AWS, Azure, or OCI, where billing and country availability are determined by that cloud provider's rules.
Privacy and the Use of Data for Training
With Cohere, it is important to distinguish Trial use from paid Enterprise/Production use.
For paid enterprise customers, Cohere provides a training opt-out in the dashboard. When this opt-out is enabled, prompts and generations are not used to train Cohere models.
Trial usage is governed by the regular Terms of Use and Privacy Policy; enterprise data commitments do not fully apply to it.
So do not send confidential production data through a free trial key just because the endpoint technically works.
Request Retention
On the SaaS Platform, Cohere deletes logged prompts and generations after 30 days by default, except when longer retention is required by law, contract, or an investigation of Usage Policy violations.
Zero Data Retention is available to enterprise customers.
With ZDR, Cohere does not log prompts and generations. Usage metadata needed to operate the service and handle billing may still be retained.
ZDR is available to enterprise customers on request and requires additional commitments from the customer.
Private Deployment Changes the Privacy Model
When the model is deployed in a private VPC or on-premises, Cohere does not receive customer prompts and generations.
This is one of the platform's strongest privacy arguments.
An organization can keep inference:
in its own AWS VPC
in Azure/GCP/OCI
in a local Kubernetes cluster
in a fully air-gapped network
while continuing to use the Cohere SDK and the same model families.
For regulated data, this is fundamentally different from using any provider's public API.
OpenAI Compatibility in PHP
You do not need a dedicated PHP SDK for Cohere. The API can be called over regular HTTP through the OpenAI-compatible endpoint.
Example:
<?php

$apiKey = $_ENV['COHERE_API_KEY'];

$payload = [
    'model' => 'command-a-plus-05-2026',
    'messages' => [
        [
            'role' => 'user',
            'content' => 'Briefly explain dependency injection.',
        ],
    ],
];

$ch = curl_init(
    'https://api.cohere.ai/compatibility/v1/chat/completions'
);

curl_setopt_array($ch, [
    CURLOPT_POST => true,
    CURLOPT_RETURNTRANSFER => true,
    CURLOPT_HTTPHEADER => [
        'Authorization: Bearer ' . $apiKey,
        'Content-Type: application/json',
    ],
    CURLOPT_POSTFIELDS => json_encode(
        $payload,
        JSON_UNESCAPED_UNICODE
    ),
]);

$response = curl_exec($ch);

if ($response === false) {
    throw new RuntimeException(curl_error($ch));
}

$data = json_decode(
    $response,
    true,
    flags: JSON_THROW_ON_ERROR
);

echo $data['choices'][0]['message']['content'] ?? '';
In Laravel:
$response = Http::withToken(config('services.cohere.key'))
    ->post(
        'https://api.cohere.ai/compatibility/v1/chat/completions',
        [
            'model' => 'command-a-plus-05-2026',
            'messages' => [
                [
                    'role' => 'user',
                    'content' => 'Briefly explain dependency injection.',
                ],
            ],
        ]
    );

$text = $response->throw()
    ->json('choices.0.message.content');
If your application needs Cohere-specific citations, documents, and native RAG features, use /v2/chat directly instead of relying only on the compatibility layer.
Store the API key only on the backend.
Official SDKs
Cohere provides SDKs for:
- Python;
- TypeScript;
- Java;
- Go.
One advantage of the SDKs is shared client logic across multiple deployment variants.
For example, the Cohere SDK can work with Cohere Platform, private deployments, and several cloud providers by changing the client configuration instead of the whole application logic.
This is a useful architectural feature for an enterprise considering a migration from a public API to private inference.
How Cohere Differs from OpenAI, Claude, and Gemini
If you look only at the chat model, Cohere may seem like a less universal platform. It does not have its own advanced video generation, real-time speech-to-speech, a consumer ecosystem on the level of Gemini, or as many hosted media models as OpenAI.
Cohere's specialization is different.
OpenAI is stronger as a general-purpose AI API with a broad range of modalities and tools.
Claude stands out particularly for coding and long-running agents.
Gemini combines multimodality with Search, Maps, and Google Cloud.
Cohere focuses on enterprise knowledge:
Parse → Embed → Search → Rerank → Command → Citations
and offers an unusually broad range of private deployment options at the same time.
For enterprise search, that may matter more than having a built-in video generator.
What Cohere Does Particularly Well
First, RAG and citations. They are not an add-on around the chat model; they are central to how Command is designed.
Second, Rerank. Cohere has made reranking a mature product in its own right, which you can use even without Command.
Third, Embed 4, with text, images, and content-rich documents in one vector space.
Fourth, Parse 5, which handles the difficult step of preparing enterprise documents for retrieval.
Fifth, private deployment. The ability to move from a public API to Model Vault, a VPC, or air-gapped on-premises deployment without changing the entire model ecosystem is not available from every provider.
Limitations
The platform also has notable weaknesses.
First, pricing for newer generative models is less transparent than OpenAI, Anthropic, or Google pricing. You can test Command A+ for free through the shared API, but production use leads to Model Vault and sales rather than standard pay-as-you-go.
Second, the Chat API remains stateless. There is no single Responses-style runtime with persistent conversations, background jobs, and hosted agent state.
Third, the media stack is much narrower: there is no full first-party image/video generation or real-time voice ecosystem comparable to the largest general-purpose AI APIs.
Fourth, open-weight licensing varies. Command A+ and North Mini Code use Apache 2.0, but other models may have non-commercial or enterprise-specific licensing.
Finally, the full Parse + Embed + vector DB + Rerank + Command architecture may be more complex than another provider's built-in file search for a small product.
Which Model and API Should You Choose?
If you need a general-purpose Cohere LLM for evaluation, start by testing Command A+.
If you need a regular production pay-as-you-go API with clear token pricing, Command A remains the more straightforward choice.
For a low-cost coding agent and private/local deployment, consider North Mini Code.
For translation, compare Command A+, Command A Translate, and the new North Small Translate separately.
For RAG, think in terms of a pipeline rather than a single model:
Parse 5
→ Embed 4
→ vector database
→ Rerank 4
→ Command A/A+
With strict data requirements, separately consider Model Vault, a private VPC, or on-premises deployment.
Conclusion
Cohere API in 2026 is quite different from the usual idea of a “ChatGPT API alternative.” A generative model is only one layer in a larger enterprise AI system.
Command A+ combines reasoning, vision, tool use, multilingual generation, and citations. North adds specialized coding and translation models. Embed 4 creates multimodal vectors, Rerank 4 improves retrieval quality, Parse 5 structures complex documents, and Cohere Transcribe handles speech-to-text.
The platform's main advantage appears when AI needs to work with a company's internal knowledge and show where each conclusion came from.
Deployment is just as important: Cohere lets you start with a free trial API, move to a production key, and then, if needed, to a single-tenant Model Vault, your own cloud VPC, or fully air-gapped on-premises deployment.
This stack may be excessive for a small consumer AI product. For enterprise search, RAG, documents, and regulated data, Cohere remains one of the market's most specialized and architecturally flexible platforms.
Official Sources
- Cohere Documentation: https://docs.cohere.com/
- Models overview: https://docs.cohere.com/docs/models
- Cohere Platform: https://docs.cohere.com/docs/the-cohere-platform
- Pricing: https://cohere.com/pricing
- Pricing explained: https://docs.cohere.com/docs/how-does-cohere-pricing-work
- Command A+: https://docs.cohere.com/docs/command-a-plus
- Command A: https://docs.cohere.com/docs/command-a
- North Mini Code: https://docs.cohere.com/docs/north-mini-code-1.0
- North Small Translate: https://docs.cohere.com/docs/north-small-translate-1.0
- Chat API: https://docs.cohere.com/docs/chat-api
- OpenAI Compatibility API: https://docs.cohere.com/docs/compatibility-api
- Tool use: https://docs.cohere.com/docs/tool-use-overview
- Structured Outputs: https://docs.cohere.com/docs/structured-outputs
- RAG Citations: https://docs.cohere.com/docs/rag-citations
- Embed: https://docs.cohere.com/docs/embeddings
- Rerank: https://docs.cohere.com/docs/rerank
- Parse: https://docs.cohere.com/docs/parse
- Cohere Transcribe: https://docs.cohere.com/docs/transcribe
- Audio Transcriptions: https://docs.cohere.com/docs/audio-transcription-quickstart
- Deployment options: https://docs.cohere.com/docs/deployment-options-overview
- Private deployments: https://docs.cohere.com/docs/private-deployment-overview
- Model Vault: https://docs.cohere.com/docs/model-vault
- Model Vault pricing: https://docs.cohere.com/docs/model-vault/standard/pricing
- Rate limits: https://docs.cohere.com/docs/rate-limits
- Going to production: https://docs.cohere.com/docs/going-live
- Enterprise Data Commitments: https://cohere.com/enterprise-data-commitments
- Security: https://cohere.com/security
Our projects
- Anilau
Web development and digital product launch. - Botmarketing
Telegram bots, mini apps, storefronts and CRM for small businesses. - vietnam.anilau.com
Listings, local services and practical guides to Vietnam. - bali.anilau.com
A marketplace for goods and services in Bali. - ceylon.anilau.com
Listings, services and practical information about Sri Lanka. - mauricetop.anilau.com
A platform for listings and information about life in Mauritius. - funlab
A platform for creating and playing AI-generated games. - aura
An AI mood diary and creative space. - drained
A Telegram Mini App for daily fatigue check-ins and recovery. - vietinfodesk
Practical guides, services and help for life in Vietnam. - frau
A cozy Nha Trang cafe profile featuring waffles, breakfast and drinks.
We work in partnership with creative agency Deep.